
Crawl depth
also called Click depthDistance from homepage
Definition
How many link steps from the homepage the crawler needed to reach a URL.
Scope, grain and dimensions
- Grain
- One value per crawled URL.
- Dimensions
- url
- Aggregation
- A per-URL attribute, not an aggregate. The crawl-budget tool filters to URLs at or beyond a depth threshold, five by default, and sorts deepest first.
- Metric type
- raw measure · link steps
Data sources
Where you'll see this
Named reports that normally include this metric.
AI bot activity reportCrawl log reportInternal linking reportTechnical SEO audit report
Skills and analyses that use it
Skills carry the judgment; the analysis verbs do the reading.
Analysis verbs
crawl_budget_wasteinternal_link_flow
Method rungs and levers
This sits on the bottom rung: if it reads badly, every measurement above it is unreliable.
levers L1 Technical & crawl healthL4 Internal linking & architecture
Ask Quattr
- "Which pages are buried deep in the site?" Simulate this →
- "Where is crawl budget going?" Simulate this →
How to read it
An architecture signal: pages that earn should not sit five clicks from the homepage. It is a property of the link graph as the crawl found it, so it responds to internal linking work rather than to content work.
Caveats, freshness and failure modes
The value is a passthrough of a column the crawler produces; the derivation lives in the crawler and is not readable in the semantic layer, so the exact traversal rules are not documented here.
The depth threshold is a caller-chosen parameter defaulting to five, so a waste list is not comparable across calls that used different thresholds.
A crawl is a snapshot on its own schedule and can disagree with a page changed since.
It reports what is REACHABLE, never what was actually fetched, that is the server logs' job.
The tool checks the crawl feed is populated first and returns a plain note when it is not.
- Freshness
- per crawl schedule, cadence is set per site; the card names the crawl it read.
Common failure modes
- Reading depth as importance.
- Comparing waste lists produced with different depth thresholds.
- Concluding a deep page is not crawled, depth is reachability, not fetch evidence.
Not the same as
The confusions that cause the most wrong decisions.
Crawl depth Bot hits Compare definitions →
Depth is what the crawl graph says is reachable; hits are what a bot actually fetched. Conflating the two is how a team concludes a page is fine because it could in principle be crawled.
Watch this metric read in a real run
All runs →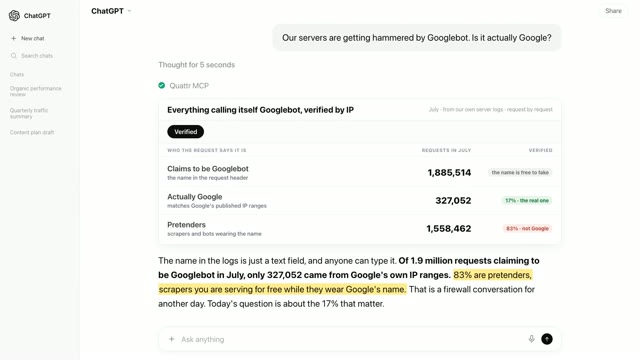 2 min 14 secMost of the Googlebot in your logs is not Google.Server logs · Crawl efficiency review◐Recreated from an anonymized session
 2 min 15 secSome of your best pages cannot be reached from your own site.Site crawl + Search Console · Linking opportunity review◐Recreated from an anonymized session
Related metrics and workflows
Verification
A definition is the smallest part of this.
The measurement matters because something acts on it. Here is the rest of the showcase, in the order most people find useful.