
Expected CTR at position
also called Modeled CTRFitted CTRCurve CTR
Definition
What this site's own history says a result should earn at a given results-page position, for a given branded, intent and device cell.
How it's calculated
The bucket weighted CTRs are fitted with a pool-adjacent-violators isotonic regression constrained monotone-DECREASING and weighted by each bucket's impressions, fitted once per branded × intent × device cell. Expected CTR at a non-integer position is linearly interpolated between the fitted bucket knots.
Scope, grain and dimensions
- Grain
- One position, evaluated on one cell's fitted curve.
- Dimensions
- position · brand · intent · device
- Required filters
- date range
- Aggregation
- One fit per segment cell; cells are never pooled into a single global curve.
- Metric type
- derived metric · share of impressions expected to click (0 to 1)
Data sources
Where you'll see this
Named reports that normally include this metric.
CTR opportunity reportSearch opportunity report
Skills and analyses that use it
Skills carry the judgment; the analysis verbs do the reading.
Analysis verbs
ctr_curve_modelstriking_distance
Method rungs and levers
A rung tells you what a movement here can and cannot explain, read the rungs below it first.
levers L3 Refresh & content quality
Ask Quattr
- "What CTR should we expect at position 4?" Simulate this →
- "What does our own click curve look like for non-brand demand?" Simulate this →
- "How much CTR would we gain moving from position 9 to 5?" Simulate this →
How to read it
The benchmark this product uses instead of a published industry table: the site's own past behaviour, made monotone so that a better position never predicts a worse rate. It is the expectation a page is measured against, not a target it is promised.
Caveats, freshness and failure modes
One blended global curve is refused by design, the branded and non-branded gap dominates click-through, so a blend would flatter one half and libel the other.
The curve is non-stationary: it drifts with results-page layout and with seasonality, so a fit from one window does not describe another.
When a row's exact cell has no fit, the substitute is the same-brand curve carrying the most impressions and, failing that, the most-data cell overall, proximity in intent or device does not enter the choice. The match kind is reported per row so a substituted curve is visible.
Buckets fitted from few instances are flagged low-confidence and the expectation drawn from them is weak.
Never an industry benchmark. Quoting a published CTR table beside this number defeats the reason it exists.
- Freshness
- 1 to 2 days behind, Google's own reporting lag. Any answer touching the last 48 hours says so on the card.
Common failure modes
- Presenting the fitted curve as an industry benchmark or a target.
- Applying a curve fitted on branded demand to a non-branded worklist without noticing the substituted cell.
- Carrying a curve across a layout change and reading the drift as performance.
Watch this metric read in a real run
All runs →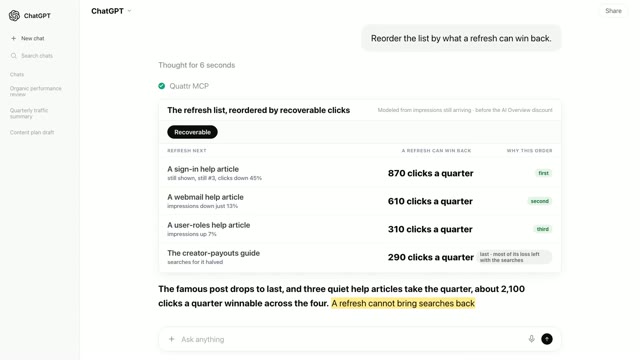
Related metrics and workflows
Verification
A definition is the smallest part of this.
The measurement matters because something acts on it. Here is the rest of the showcase, in the order most people find useful.