
AI visibility
How to know if AI crawlers can reach your content
ai-crawler-readiness a saved expert workflow your assistant follows, in Claude, ChatGPT or Cursor
Are AI crawlers actually fetching the content you want cited? Server-log truth on GPTBot, ChatGPT-User, ClaudeBot, PerplexityBot and friends, crossed with indexability and orphan status on your citation targets, "you can't be cited if you were never crawled".
Try it
are AI crawlers reaching us
Private beta Part of the quattr-ai-search plugin, rolling out org by org. Request access ↗
Say any of these
are AI bots crawling usGPTBot activityAI crawler readinessis ChatGPT fetching our pagesare we blocking AI crawlersAI bot coverage
You never name the skill or a tool, the assistant routes on what you asked. These are the phrasings it recognises for this one.
And when it stays out of the way
Not for a bare bot-traffic count ("how many times did GPTBot crawl us", a single tool read), for citation counts themselves (ai-citation-monitoring), for classic-Googlebot crawl-budget questions, or for the full technical sweep (technical-health-audit).
Use it instead of technical-health-audit when AI bots are the subject; use ai-citation-monitoring instead for what the answers cite.
What it runs
ai_crawler_analysisbot_verificationindexation_gap_diagnosisorphan_pages
4 governed analyses, composed and scoped for you. Named here for transparency, not because you have to ask for them.
The numbers behind it
Metrics it reads, each defined in the reference
Bot hitsCrawler readinessIncoming internal linksIndexability flagsUnique pages crawledVerified versus spoofed Googlebot
Reports these numbers feed
AI bot activity reportCrawl log reportInternal linking reportTechnical SEO audit report
What it refuses to do
- Crawl activity is server-log truth, NOT citations, never present fetch counts as visibility (the two verbs' families stay distinct).
- Per-bot blocking advice is a per-surface business decision with named costs, present the documented trade-offs, don't prescribe a blanket allow/deny.
- Unverified bot traffic is excluded from verdicts, and said so.
What the answer looks like
Are AI bots crawling us?
Analysis plan, every step, resolved for you
- Routed to the governed workflow
ai-crawler-readiness - Dates bound explicitly
Jul 1 to Jul 31, 2026 - 4 analyses queued in parallel
ai_crawler_analysis · bot_verification · indexation_gap_diagnosis · orphan_pages - Honesty gates armed
scope echo · freshness
One source can't answer this, they join
- Server logsAI bot fetches, status codes
- Site crawlindexability, orphan status
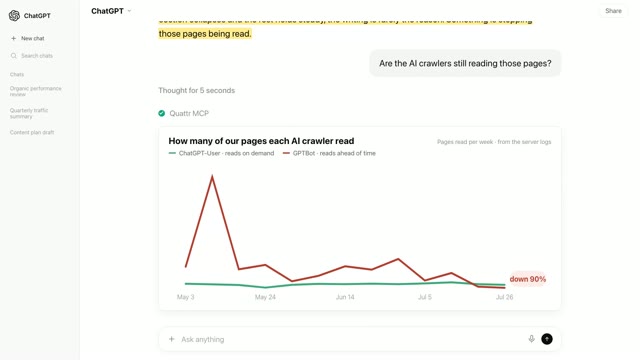
AI bots fetched 8.1K pages in July, but a third of your citation targets were never crawled.
- AI bot fetches
- 8,140 ▲ +22% GPTBot 4.4K · ClaudeBot 1.9K · PerplexityBot 1.1K
- Citation targets crawled
- 67% 38 of 57 priority pages fetched by any AI bot
- Never fetched
- 19 pages 6 are orphans, no internal links point to them
Jul 1 to Jul 31, 2026
⚠ Observationalas of Aug 2, 2026 (logs load nightly)IllustrativeOpen in Quattr ↗
You can't be cited if you were never crawled, link the 6 orphaned targets and re-check in two weeks.
A simulated conversation on fictional data. Scope, freshness and the ⚠ Observational marker are attached by the same director that renders every demo here, not written by hand.
See this Skill inside a real analysis
All runs →A recorded run where this Skill does the work, the prompts as typed, and the decision that came back.
Want this Skill running on your own accounts? Every Quattr customer works with an AI Search Strategist who sets it up with you.